Free resource
Built in a week. Runs every morning. Scans 500+ articles, updates a knowledge graph, picks the strongest angle from your domain, writes a brief in your voice, fact-checks its own work. Your expertise is the engine. AI is the infrastructure.
One email with a walkthrough of what each file does and how to adapt it.
What is inside
How it works
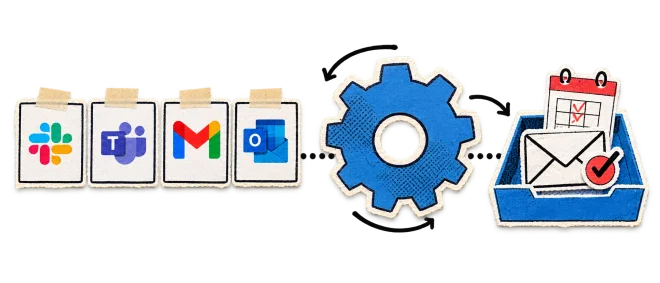
The agent starts where any analyst starts: reading everything. It pulls articles from your configured source feeds (RSS, YouTube, databases) and clusters them by topic. Same story showing up across multiple sources? That's a signal.
You configure the sources in ecosystem.json. RSS feeds, YouTube channels, custom databases. The agent doesn't scrape the internet: it reads what you tell it to watch.
592 articles scanned / 6 categories / 5 cross-source clusters identified
This is what separates it from a summarizer. The knowledge graph is persistent memory across days. Companies, people, products, events, and the relationships between them.
Day 1, the graph is empty. Day 5, the agent knows a company's last three announcements. Day 30, storylines have arcs. Continuity emerges from structure, not token windows.
14 companies / 7 people / 9 products / 9 storylines tracked
+8 entities added today / +2 storylines created
You define 8-12 analytical positions in thesis.md. Not topics (those change daily). Positions: recurring arguments about your domain that stay stable for months. The interpretation layer between raw news and finished analysis.
The agent matches today's clusters against your positions and picks the one with the strongest evidence. It checks the last 3 deliverables to avoid repeats.
A thesis turns a summarizer into an analyst. Without positions, the agent compresses information. With positions, it argues a case using today's evidence.
Angle: #2 Deciding beats building
Sources: 5 articles from HN, TechCrunch, rudel.ai
One API call. Cost: eight tenths of a cent. The agent loads your voice rules from CLAUDE.md and writes the brief. Length sampled from a configurable range.
You control the voice through two layers: style rules in CLAUDE.md (sentence length, vocabulary, rhythm) and example pieces in the examples/ directory that the agent uses as reference.
The same week a blog post called "Shall I implement it? No" hit 563 points on Hacker News, Benchmark dropped fifty million dollars on a company whose entire pitch is making everyone a builder. Both of those things are right.
30+ phrases across 5 kill categories. Every sentence checked. Every factual claim verified against the source articles in the knowledge graph. If it sounds like AI wrote it, it gets rewritten.
7 claims verified against source articles / 0 corrections / 0 slop phrases
Brief saved with structured frontmatter (type, angle, sources, cost). Knowledge graph updated with references. Git committed and pushed.
177 API requests total. The brief itself was $0.008. The other five dollars was the agent reasoning about what to write. That's the interesting number.
Total: $5.11 / Brief: $0.008 / Reasoning: $5.10
Requests: 177 / Duration: ~18 min
This agent took a week to build. Now it runs every morning without intervention. Scans the ecosystem, updates its memory, picks the strongest angle, writes in a specific voice, verifies its own facts, and delivers.
Everyone has access to the same AI. The difference between "AI works" and "AI did nothing" is whether someone built the system: the memory, the tools, the pipeline connecting AI to the actual work.
Free resource
CLAUDE.md, knowledge graph, slop kill list, runner script, PRD. The full system behind this agent. Same shape we adapt per tenant.
CLAUDE.mdecosystem.jsonai-slop-phrases.mdralph.shprd.json